 KnowForge
快速入门
非结构化数据快速入门
 师成· 更新于 2026-09-29· 阅读 19 分钟· 0 次阅读
登录后可跨设备保存划线和私人笔记登录
人工智能与机器学习流水线(RAG、推荐、多模态搜索)需要将向量嵌入、原始字节与结构化元数据并排存储和查询。Hudi 的 VECTOR 和 BLOB 列类型让你可以在同一张事务表中保存所有这些数据。本指南将带你完整走通整个流程:你将在同一张 Hudi 表中存储图像嵌入(VECTOR)和原始图像字节(BLOB),然后通过一条 SQL 查询执行 top-K 相似度搜索,并将匹配到的图像物化返回。
提示
想在本地试试吗?本指南还有一个可交互的 Jupyter notebook 版本。下载 notebook,在你的机器上端到端运行它。
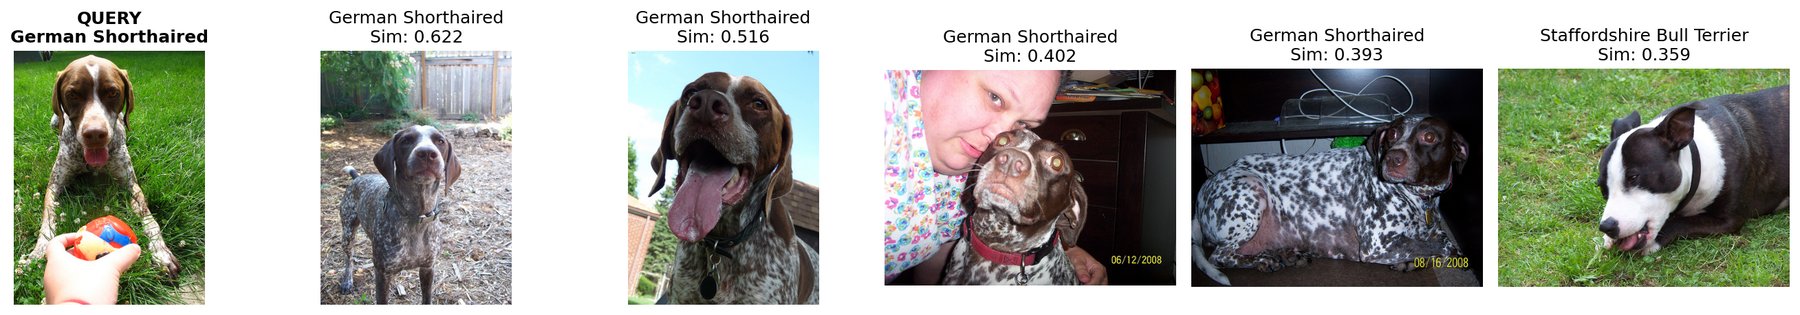
示例输出:一张德国短毛指示犬的查询图像(左),以及由 hudi_vector_search 找到的五张最相似图像及其余弦相似度分数。原始图像字节在同一查询中通过 read_blob() 直接物化返回。
前置要求
| 要求 | 版本 |
|---|---|
| Java | 11+ |
| Python | 3.10 – 3.12 |
| Apache Spark | 3.5.x |
| Hudi Spark bundle | 1.2.0+ |
pip install pyspark==3.5.* pyarrow>=14.0.0 \
  torch>=2.3.0 torchvision>=0.18.0 timm>=1.0.9 \
  scikit-learn>=1.4.2 numpy>=1.26.0 pillow>=10.3.0 matplotlib>=3.8.0
1. 使用 Hudi 启动 Spark
import os
from pathlib import Path
from pyspark.sql import SparkSession

HUDI_JAR = os.getenv("HUDI_BUNDLE_JAR", "hudi-spark3.5-bundle_2.12-1.2.0.jar")

spark = (
    SparkSession.builder
    .appName("Hudi-Unstructured-Data-QuickStart")
    .config("spark.jars", HUDI_JAR)
    .config("spark.serializer", "org.apache.spark.serializer.KryoSerializer")
    .config("spark.sql.extensions",
            "org.apache.spark.sql.hudi.HoodieSparkSessionExtension")
    .config("spark.sql.catalog.spark_catalog",
            "org.apache.spark.sql.hudi.catalog.HoodieCatalog")
    .getOrCreate()
)
2. 加载图片并生成向量
加载 Oxford-IIIT Pet 数据集(37 个品种),并使用 MobileNetV3 生成 1024 维的向量。
import io, torch, timm, numpy as np
from sklearn.preprocessing import normalize
from PIL import Image
from torchvision.datasets import OxfordIIITPet

N_SAMPLES = 250

ds = OxfordIIITPet(root="~/.cache/torchvision", split="trainval", download=True)
indices = np.random.default_rng().choice(len(ds), size=N_SAMPLES, replace=False)

# Collect images as PNG bytes
data = []
for idx in indices:
    img, label = ds[int(idx)]
    buf = io.BytesIO(); img.convert("RGB").save(buf, format="PNG")
    data.append({
        "image_id": f"pets_{int(idx):06d}",
        "category": ds.classes[label],
        "label":    int(label),
        "image_bytes_raw": buf.getvalue(),
    })

# Generate embeddings
model = timm.create_model("mobilenetv3_small_100", pretrained=True, num_classes=0)
model.eval()
cfg = timm.data.resolve_model_data_config(model)
transform = timm.data.create_transform(**cfg, is_training=False)

batch = torch.stack([
    transform(Image.open(io.BytesIO(d["image_bytes_raw"])).convert("RGB"))
    for d in data
])
with torch.no_grad():
    feats = normalize(model(batch).numpy())

for i, d in enumerate(data):
    d["embedding"] = feats[i].tolist()

DIM = feats.shape[1]  # 1024
3. 创建表并插入数据
为嵌入向量声明 VECTOR(1024),为原始图像字节声明 BLOB。
from pyspark.sql import Row
from pyspark.sql.types import *

# Register as a Spark temp view
schema = StructType([
    StructField("image_id",        StringType(),                               False),
    StructField("category",        StringType(),                               False),
    StructField("label",           IntegerType(),                              False),
    StructField("image_bytes_raw", BinaryType(),                               False),
    StructField("embedding",       ArrayType(FloatType(), containsNull=False), False),
])
rows = [Row(d["image_id"], d["category"], d["label"],
            d["image_bytes_raw"], d["embedding"]) for d in data]
spark.createDataFrame(rows, schema).createOrReplaceTempView("staging")
CREATE TABLE pets (
image_id STRING,
category STRING,
label INT,
image_bytes BLOB,
embedding VECTOR(1024)
) USING hudi
LOCATION '/tmp/hudi_pets'
TBLPROPERTIES (
primaryKey = 'image_id',
preCombineField = 'image_id',
type = 'cow',
'hoodie.table.base.file.format' = 'parquet',
'hoodie.write.record.merge.custom.implementation.classes'
= 'org.apache.hudi.DefaultSparkRecordMerger'
);
INSERT INTO pets
SELECT image_id, category, label,
named_struct(
'type', 'INLINE',
'data', image_bytes_raw,
'reference', cast(null as struct<
external_path:string, offset:bigint,
length:bigint, managed:boolean>)
) AS image_bytes,
embedding
FROM staging;注意:
VECTOR(1024)存储固定维度的嵌入向量,用于相似度搜索。BLOB以内联方式存储原始图像字节。对于大型对象,请使用OUT_OF_LINE仅存储一个指针。read_blob()会透明地解析这两种模式。
4. 使用 read_blob() 物化 BLOB
read_blob() 是 Hudi 的 BLOB 访问器。向它传入一个 BLOB 列,即可返回原始 binary 数据。无论是内联字节还是非行内引用,其工作方式都完全相同。
SELECT image_id, category,
       length(read_blob(image_bytes)) AS byte_count
FROM pets
LIMIT 5;
+-----------+--------------------+----------+
| image_id| category|byte_count|
+-----------+--------------------+----------+
|pets_002081| Beagle| 249983|
|pets_003404| Shiba Inu| 349745|
|pets_001939| American Bulldog| 267667|
|pets_002457|English Cocker Sp..| 364492|
|pets_003538|Staffordshire Bul..| 427728|
+-----------+--------------------+----------+
这些图片字节由 read_blob() 检索并解码回 PNG 格式。经过 Hudi BLOB 列的往返转换是无损的。
5. 在一个查询中同时进行向量搜索与 BLOB 检索
hudi_vector_search 按余弦相似度返回 top-K 最近邻;read_blob() 仅为匹配的行物化图片字节。
SELECT image_id,
       category,
       read_blob(image_bytes) AS resolved_bytes,
       _hudi_distance
FROM hudi_vector_search(
    '/tmp/hudi_pets',        -- table path
    'embedding',             -- VECTOR column
    ARRAY(0.12, -0.03, ...), -- query embedding (1024 floats)
    5,                       -- top-K
    'cosine'                 -- distance metric
)
ORDER BY _hudi_distance;
+-----------+--------------------+-----------+
| image_id| category| distance |
+-----------+--------------------+-----------+
|pets_002575| German Shorthaired| 0.378 |
|pets_000703| German Shorthaired| 0.484 |
|pets_002562| German Shorthaired| 0.598 |
|pets_002556| German Shorthaired| 0.607 |
|pets_003538|Staffordshire Bul..| 0.641 |
+-----------+--------------------+-----------+
查询:德国短毛指示犬(左)。按余弦相似度排名的前 5 条结果。
6. 可视化结果
import matplotlib.pyplot as plt
from PIL import Image

fig, axes = plt.subplots(1, len(results) + 1, figsize=(3 * (len(results) + 1), 3.2))

# Query image
axes[0].imshow(Image.open(io.BytesIO(query_bytes)))
axes[0].set_title("QUERY", fontweight="bold"); axes[0].axis("off")

# Top-K matches
for i, row in enumerate(results):
    img = Image.open(io.BytesIO(bytes(row["resolved_bytes"])))
    sim = 1.0 - float(row["_hudi_distance"])
    axes[i+1].imshow(img)
    axes[i+1].set_title(f"{row['category']}\nSim: {sim:.3f}")
    axes[i+1].axis("off")

plt.tight_layout()
plt.savefig("hudi_vector_search_results.png", dpi=150)
下一步
| 主题 | 链接 |
|---|---|
| 完整交互式笔记本 | 00_main_demo.ipynb |
| VECTOR 类型参考 | SQL DDL 中的 VECTOR · SQL DML · DataFrame 写入 · SQL 查询中的 hudi_vector_search |
| BLOB 类型参考 | SQL DDL 中的 BLOB · SQL DML · DataFrame 写入 · SQL 查询中的 read_blob() |
| VARIANT 类型 | SQL DDL 中的 VARIANT · SQL DML · DataFrame 写入 · 查询 VARIANT |
| Lance 文件格式 | 存储布局 → Lance · DataFrame 写入 |
| AI 湖仓用例 | 用例 → AI 湖仓 |
评论
登录后参与评论
正在加载评论…